The notes folder has 40 markdown files and search is already a grep ritual. You’ve been patching in ad-hoc filters with bash scripts to sort notes by creation date and tag, and the script broke yesterday when you added a note with a comma in the filename. At this point, you’ve probably wondered if it’s finally time to stop hacking file-based workarounds and reach for a real database. The line between unnecessary overengineering and solving a real pain point is thinner than you think, and the below decision table takes the guesswork out of when to upgrade your data layer.
Build Next Stack editors
Queries you cannot fake with a JSON file
For many small side projects, a single JSON file or set of markdown files works perfectly. You read the full file once when your app starts, write the full file once when you save changes, and you never have to think about database configuration. That stops working when you need to run queries that require scanning or modifying only a subset of your data, rather than the entire dataset.
Common queries you can’t efficiently fake with static files include counting records that match three separate criteria, updating a single field across 20 records without touching the rest of your data, or avoiding data loss if your app crashes mid-write. If you find yourself writing 100+ lines of custom logic to handle a basic filter or update, you’re past the point where static files make sense.
Below is a decision table to compare your options based on real use cases, no hype involved:
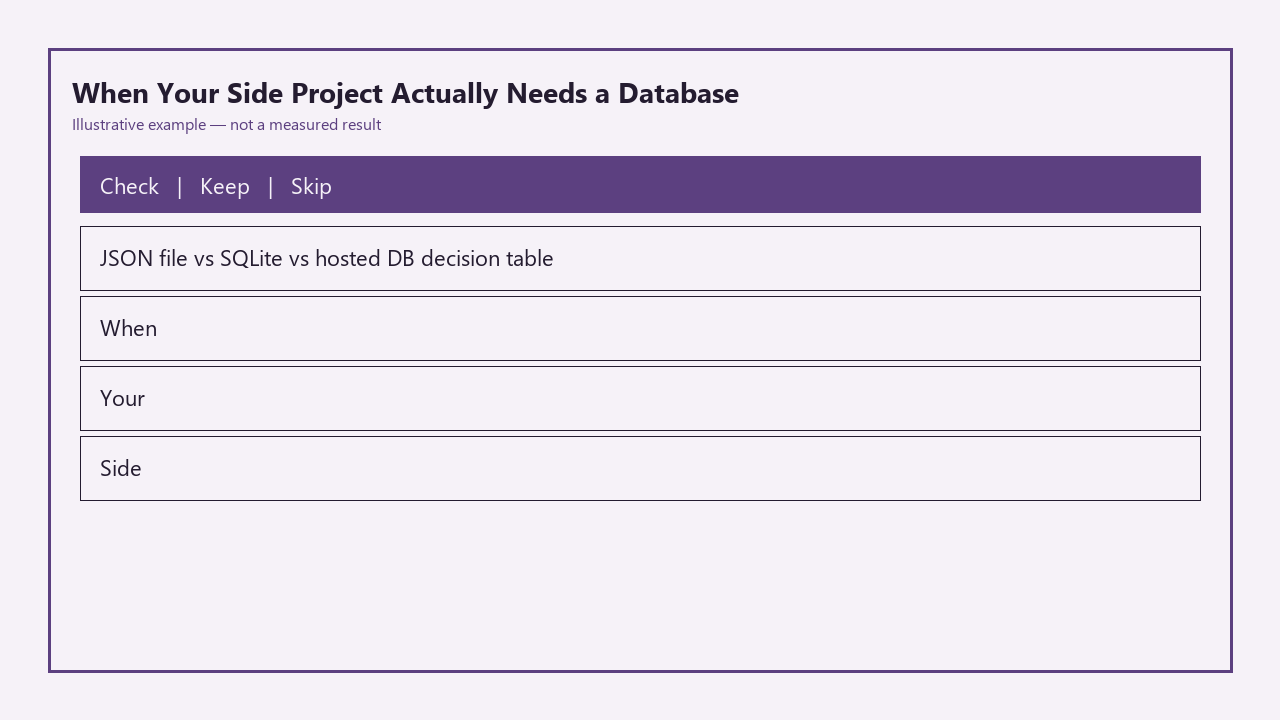
| Use case | JSON file | SQLite | Hosted database |
|---|---|---|---|
| Single user, <1000 total records, no concurrent writes | Yes, no extra work needed | Works, but overkill for this stage | Severe overkill, unnecessary cost |
| Regularly filter/sort on 2+ fields (e.g. show all notes tagged #work created in the last 7 days) | Limited, requires writing custom loop logic for every query | Yes, 1-line SQL query handles it natively | Yes, same SQL support as SQLite |
| Need partial updates (e.g. change the status of one task without rewriting all data) | No, full file rewrite required every save, risk of corruption if write is interrupted | Yes, atomic updates only modify the specific record you target | Yes, atomic updates included by default |
| Multiple concurrent writers (e.g. two users editing the same project, a cron job writing while a user makes changes) | No, file locks will cause crashes or lost data | Limited, only supports one write at a time, works for low-frequency concurrent writes | Yes, built-in support for hundreds of concurrent writers |
| Need to access data from 2+ separate devices/servers (e.g. use your app on your laptop and phone) | No, requires manual file sync that risks overwrites | Limited, works if you sync the SQLite file via cloud storage, but risk of conflict | Yes, built-in sync across all connected clients |
| Offline-first access required | Yes, file is stored locally | Yes, single file works entirely offline | Limited, requires caching layer for offline use |
SQLite as the first real store on a laptop
If your use case falls into the SQLite column of the decision table, you’re in luck: SQLite requires almost zero setup to start using. It’s a file-based relational database that runs entirely on your local machine, no server process or credentials required. Every major programming language has built-in or one-click install support for SQLite, so you won’t spend hours configuring dependencies just to run a query.
Example measurement: A single SQLite file can support up to 140TB of data and 1 million write operations per day, which is more than enough for 99% of solo side projects for their first full year of active use. You can back up your entire database by copying the single SQLite file to a cloud drive, and you can run full SQL queries without paying for any hosted services. Many production apps run entirely on SQLite for years, especially if they’re only accessed by a single user or deployed to a single VPS with low concurrent write volume.
You don’t need to learn an ORM or complex schema management tool to use SQLite, either. You can start with a single table that matches the exact structure of your old JSON file, so you don’t have to rewrite your entire app logic to switch over.
Hosted databases that wait until two writers exist
There’s a pervasive myth that you need a hosted database to run a “real” side project, but that’s only true once you have multiple writers accessing your data at the same time. A writer is any process or user that modifies your data: that could be a second user you shared your app with, a cron job that imports data every hour while you’re also using the app, or you accessing the app from both your laptop and your phone.
Hosted databases like Supabase, Neon, or PlanetScale handle concurrent writes out of the box, sync data across all connected devices automatically, and manage backups and uptime so you don’t have to. Most have free tiers that support up to 100,000 rows of data, which is enough for most small shared projects. Illustrative example: If you’re building a personal habit tracker that only you use on your laptop, a hosted database is a waste of time and money. If you add a shared grocery list feature for you and your partner, that’s two concurrent writers, so it’s time to upgrade.
Migration fear that shows up on night three
The most common pushback against moving from static files to a database is fear of schema migrations: the process of changing your data structure after you’ve already stored real data. This fear usually shows up on the third night of working with a database, when you realize you forgot to add a “due date” field to your tasks table and you don’t want to lose all the data you’ve already entered.
The good news is migrations are far less scary for small side projects than they are for large enterprise apps. For SQLite, you can handle migrations with simple numbered SQL files stored in your project repo, run in order every time you deploy changes. Always make a copy of your SQLite file before running a migration, so you can roll back in 10 seconds if something breaks. For hosted databases, almost all providers offer point-in-time recovery, so you can roll your entire database back to any minute before you ran a bad migration if you make a mistake. You don’t need to use complex migration tools unless you want to: a 3-line SQL script to add a column works perfectly for 90% of side project use cases.
Keep-file rule until a join actually appears
A common mistake people make when switching to a database is over-normalizing their schema right away, splitting data into 5+ separate tables that require complex joins to query, even when they don’t need it. The keep-file rule solves this: you keep your data model as close to your original file structure as possible, with as few tables as possible, until you have a concrete, real-world query that requires a join to run efficiently.
For example, if you’re building a note taking app, you can store all your tags as a comma-separated list or array in a single notes table for months, rather than splitting tags into a separate table that requires a join to query. You only need to split tags into their own table when you want to run a query that counts how many times each tag is used across all 10,000 of your notes, which would be slow to run with a custom loop on a single table. This rule lets you move fast and avoid unnecessary complexity until you actually need it.
Tonight, open your current side project and run through the decision table above to see if you’re still using static files for a use case that would be 10x easier with SQLite, or wasting money on a hosted database you don’t actually need yet.