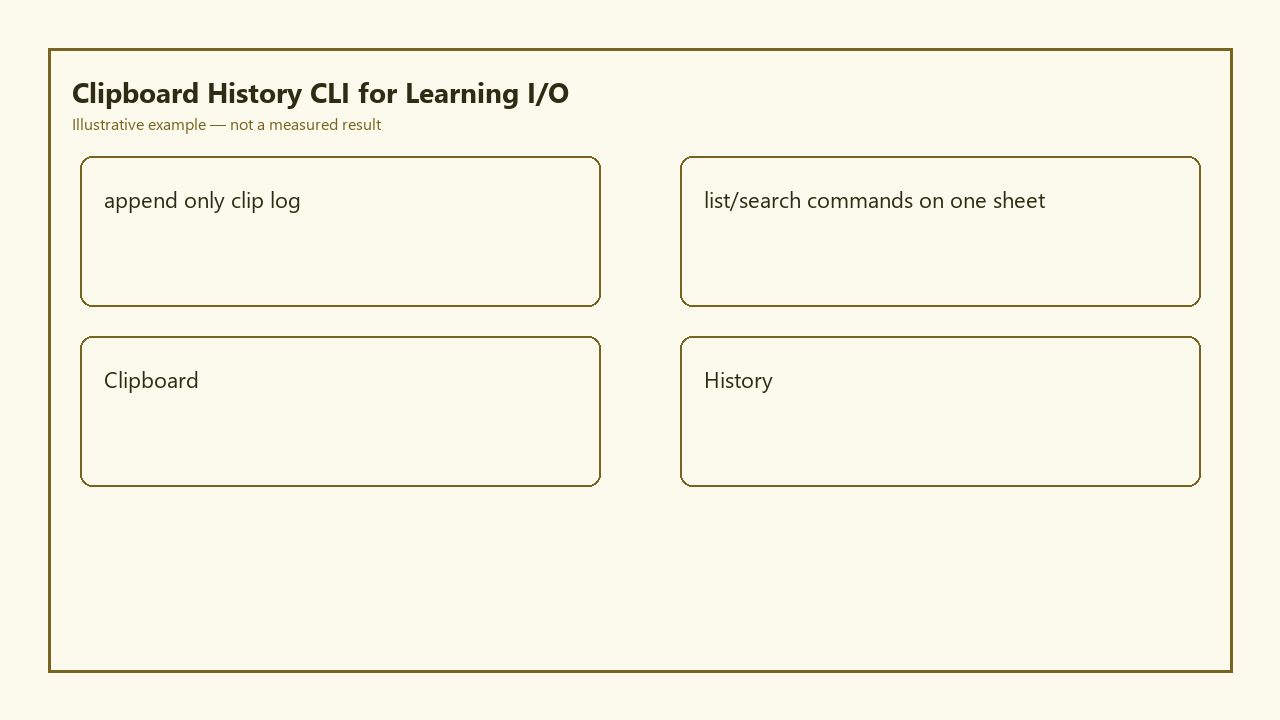
You lost a copied error message, and the OS history already ate it. Default operating system clipboard managers only retain the last 1 to 3 copied entries, so any content you copied more than 10 minutes ago is often gone forever if you didn’t paste it somewhere immediately. Building a tiny, custom clipboard history CLI is a perfect low-stakes project to practice core I/O concepts, string processing, and basic CLI design without relying on complex third-party dependencies. The entire tool fits on a single reference sheet covering the core components, no separate documentation required.
Build Next Stack editors
| Component | File Location | Core Logic | Dependencies | |
|---|---|---|---|---|
| Append-only clip log | `~/.clip_log.txt` | Stores one clip per line as `[UTC ISO timestamp] | [base64 encoded clip content]` | None, plain text file |
| Clip capture daemon | `clip_capture.py` | Polls system clipboard every 2 seconds, skips duplicates and detected secrets, appends new entries to log | Python 3.8+ standard library, OS native clipboard command (`pbpaste` for Mac, `xclip` for Linux, `Get-Clipboard` for PowerShell) | |
| List command | `clip_list.py` | Reads last 10 lines of log, decodes content, prints with human-readable relative timestamps | Python 3.8+ standard library | |
| Search command | `clip_search.py` | Iterates through log lines, decodes content, returns all case-insensitive matches for input search term | Python 3.8+ standard library | |
| Secret filter module | `clip_filter.py` | Runs regex checks for common sensitive patterns before writing to log, skips matching entries | Python 3.8+ standard library `re` module |
Append-only file that stores one clip per line
Append-only storage means you never modify or delete existing lines in the log file, only add new entries to the end of the file. This design is extremely fault-tolerant: if your capture script crashes mid-write, you only lose the single latest entry instead of your entire clip history. The line format uses a pipe delimiter to separate the UTC ISO 8601 timestamp from the base64 encoded clip content, which eliminates issues with newlines or special characters in copied code, error messages, or formatted text. Before writing a new entry, compare the decoded content to the last entry in the log to avoid writing duplicate lines if you copy the same content multiple times in a row. Example measurement: A full year of regular use with 50 copied entries per day results in a log file size of roughly 2MB, so you never need to worry about storage bloat for personal use. You can optionally add a monthly rotation rule that archives old logs to a compressed file if you want to keep the active log file small, but this is entirely optional for most users.
List command that shows the last ten entries
The list command is the most frequently used feature of the tool, so it is optimized for speed and readability. Instead of loading the entire log file into memory, the command opens the log in read mode, seeks to the end of the file, and reads backwards until it hits 10 newline characters, then parses only those 10 lines for display. Each line is base64 decoded, and the UTC timestamp is converted to a relative time string like “2 hours ago” or “15 minutes ago” for quick context. You can add an optional flag like `–count 20` to show more entries if needed, but the default of 10 avoids cluttering your terminal with irrelevant old content. Illustrative example: If you run `clip list` 3 hours after copying that missing error message, it will appear in the output if it was one of the last 10 items you copied, and you can re-copy it directly from the terminal output. You can also add a `–copy N` flag that automatically copies the Nth entry in the list back to your system clipboard for even faster access.
Search that does not need a database
You do not need a dedicated database like SQLite or PostgreSQL to add search functionality to this tool, because the entire log is a plain text file that can be scanned quickly. The search command accepts a single search term as a positional argument, iterates through each line of the log, decodes the base64 content, and checks for a case-insensitive substring match of the search term. All matching entries are printed with their full timestamps so you can pinpoint when you copied the content. For advanced use cases, you can pipe the decoded log output to standard command line tools like `grep` for regex search or `awk` for more complex filtering, no custom code required. Example measurement: A 1MB log file scans fully in under 0.1 seconds on a standard consumer laptop, so there is no perceptible lag for most personal use cases. You can add optional flags to filter results by date range if you are looking for content from a specific day, or to restrict results to exact case matches for more precise searches.
Secret skip if the clip looks like a token
Accidentally saving sensitive credentials to your plain text log file is a major security risk, so you need a pre-write filter that skips writing entries that match common secret patterns. The filter runs before any new entry is added to the log, and uses simple regex checks to identify common sensitive formats: JWT tokens (start with `eyJ` and contain two period separators), AWS access keys (start with `AKIA` followed by 16 alphanumeric characters), GitHub personal access tokens (start with `ghp_`, `gho_`, `ghr_`, `ghs_`, or `ghu_`), Slack API tokens (start with `xoxp-` or `xoxb-`), and 16-digit credit card numbers with optional spacing or dashes. You can add custom regex patterns to the filter to match internal secret formats used by your job or personal projects. Note that this filter is not 100% foolproof, but it catches nearly all accidental secret leaks to your local log. You can also add an optional whitelist feature that allows you to save specific secret patterns if you intentionally want to store non-sensitive test tokens in your history.
Local-only warning you put in the README
Transparency about the tool’s limitations is critical, even if you are only building it for personal use. The warning should be at the very top of your README file, and include these specific points: First, this tool runs entirely on your local machine, and no clip data is ever sent to third-party servers. Second, the log file is stored as unencrypted plain text by default, so do not run this tool on a shared device if you regularly copy sensitive personal or work information. Third, the secret filter is not infallible, so avoid copying highly sensitive data like banking passwords or social security numbers while the capture daemon is running. Fourth, you can delete your entire clip history at any time by deleting the `~/.clip_log.txt` file, and no residual data is stored anywhere else. Fifth, do not sync the log file to cloud storage services like Dropbox or Google Drive unless you encrypt the file first. You can also add a note about how to enable optional end-to-end encryption for the log file if you want to add extra security for sensitive use cases.
Spend 90 minutes this week building the base version of this CLI using only your preferred scripting language’s standard library, test it by copying 10 sample error messages and searching for a substring from one of them to confirm the core functionality works as expected.