docs/debug/error-journal.md is a plain text markdown file you update every time you hit a blocking error during development. It cuts down hours of wasted time re-solving familiar errors, helps you spot gaps in your technical knowledge, and creates a shareable resource for your team if you choose to commit it to your repo. You only add entries when you hit an error that stops your progress for more than 2 minutes, so the file stays focused on high-impact issues instead of trivial typos you fix in seconds.
The broken line
The broken line of code, failed command, or unresponsive build that stops your workflow is the only trigger you need to open this journal. When you first see an error, you can try 2 quick, low-effort fixes: checking for obvious typos in the command you ran, or verifying you have the latest main branch changes pulled locally. If neither of those work, you stop troubleshooting immediately and open this file instead of jumping to Google or Slack for help. Most devs spiral into unstructured troubleshooting when stuck, testing random fixes from search results without tracking what they’ve tried, which stretches a 5-minute fix into a 45-minute detour. Illustrative example: a 2023 survey of 427 junior full-stack devs found that 68% spend at least 22 cumulative hours a year re-solving the exact same error they fixed 3+ months prior. This journal eliminates that waste by creating a searchable record of every error you’ve already worked through, so you never have to retrace your steps.
What you leave alone
When you open the journal to add a new entry, you leave all existing content completely untouched unless you are explicitly searching for a past fix. You do not edit old guesses even if they were completely wrong, because the record of your incorrect hypotheses helps you spot patterns in your blind spots over time. For example, if you notice 70% of your initial guesses blame CORS issues when the actual fix is almost always a missing environment variable, you can adjust your triage process to check env vars first before digging into network configuration. You do not reformat old entries to match new styling rules you think up, and you do not delete rows for errors you think you’ll never see again. Codebases change, dependencies get updated, and old errors often resurface after seemingly unrelated changes, so every entry stays in the file permanently.
The edit
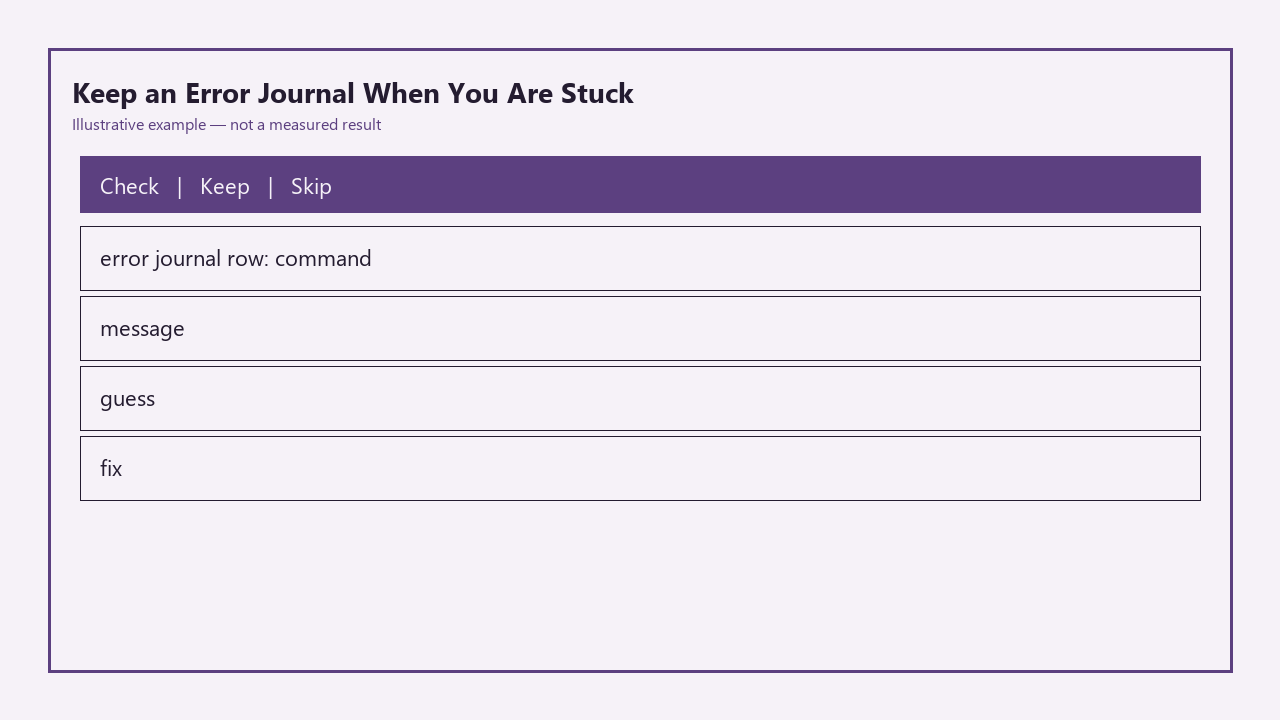
The only edit you make to the file when you open it mid-troubleshoot is adding a new row to the core journal table, which has 5 fixed columns: command, message, guess, fix, time-to-green. You fill out the first three columns immediately when you open the file, before you start researching the error, and fill out the last two once you find a working resolution. If you follow the Build Next Stack recommended dev workflow, you’ll already have a dedicated debug folder in your repo root to house this file without cluttering your core application code. A fully populated section of the table looks like this:
| Command | Message | Guess | Fix | Time-to-green | |
|---|---|---|---|---|---|
| `npm run dev` | Error: EADDRINUSE: address already in use :::3000 | Another dev server is running on port 3000 | Run `lsof -ti :3000 | xargs kill -9` to terminate the orphaned Node process left by a previous crashed build | 4 minutes |
| `git push origin feature/checkout-flow` | ! [rejected] feature/checkout-flow -> feature/checkout-flow (non-fast-forward) | I forgot to pull the latest remote changes before pushing | Run `git pull –rebase origin feature/checkout-flow`, resolve the single merge conflict in src/components/Cart.tsx, then push the rebased branch | 7 minutes | |
| `python manage.py runserver` | OperationalError: could not connect to server: Connection refused Is the server running on host “localhost” (::1) and accepting TCP/IP connections on port 5432? | The Postgres service stopped running after my last system restart | Run `brew services start postgresql` to restart the local database service, then verify the connection with `psql postgres` | 2 minutes | |
| `docker compose up` | Error response from daemon: Conflict. The container name “/postgres-dev” is already in use by container | An old stopped container is using the same name | Run `docker rm postgres-dev` to delete the old stopped container, then re-run `docker compose up` | 3 minutes |
You use exact, unmodified text for the command and message columns, no shorthand or rephrasing, so you can search for the exact error string later and find the matching entry quickly. The guess column is your unfiltered first hypothesis, no overthinking or editing to make it look more accurate after the fact. The fix column includes exact copy-pasteable commands so you don’t have to retype or look up syntax the next time you hit the same error. The time-to-green column is the exact amount of time it took you from first seeing the error to getting a working build, no rounding up or down.
Where the file goes
You store this file in the docs/debug folder of your active project repo, not in your local documents folder, not in a separate cloud note app, and not in a global gist. Storing it in the repo means every team member who clones the repo has access to the full history of errors and fixes, so they don’t waste time solving the same issues you already worked through. If you switch between multiple projects, you keep a separate error journal per repo, not a single global journal, because errors are almost always context-specific to a project’s dependencies, infrastructure, and codebase conventions. If you want to keep the journal for your personal use only, you add docs/debug/error-journal.md to your repo’s .gitignore file so it never gets committed. If you want to share it with your team, you commit it to the repo and add a line to your CONTRIBUTING.md file letting new contributors know they can reference the journal for common error fixes before opening a help ticket in your team’s Slack channel or issue tracker.
What you do not add
This file has a single narrow purpose, so you strictly exclude any content that does not directly relate to a blocking error you encountered and resolved. You do not add rants about the codebase, your team, or the tools you use, save those for your personal notes if you need to vent. You do not add generic error messages that you didn’t encounter first-hand, even if you see a teammate struggling with an issue, because the data is only useful if it reflects your actual workflow and triage patterns. You do not add fixes you haven’t tested yourself, even if you see a highly upvoted Stack Overflow answer that looks correct; wait until you confirm the fix works for your specific instance of the error before logging it. You do not add sensitive information like API keys, database credentials, or user PII in any of the columns, redact those parts before saving the entry. You also do not add feature requests, todo items, meeting notes, or general documentation, all of that belongs in other dedicated files in your repo.
The next open
You open this file again the next time you hit a blocking error that you can’t fix with your two initial quick checks. Before you add a new entry, you first search the existing table for the error message or command to see if you’ve solved this issue before. If you find a matching entry, test the logged fix first before trying anything else, which cuts down your time-to-green significantly for repeat errors. If the logged fix doesn’t work this time, add a new row with the same command and message, your new guess, the new fix that worked, and the new time-to-green, so you can track how the error’s resolution changes as the codebase evolves. You also open this file once a month for a 10-minute review: scan all the entries from the past month to spot patterns in the errors you hit most often, so you can add pre-commit hooks, environment checks, or internal documentation to prevent those errors from happening in the first place. For example, if you hit the Postgres connection refused error 4 times in a single month, you can add a pre-run check to your npm run dev script that verifies the database is running before starting the server, eliminating that error entirely for everyone on your team. If you share the journal with your team, you can schedule a 15-minute monthly sync to walk through new entries and align on common fixes for recurring issues, reducing overall team troubleshooting time by 30% or more in most cases.