`docs/db-decision-framework.md` is empty.
You created the file this morning after spending three hours fixing corrupted user data in your plant care side project, where two beta testers updated the same plant’s water log at the same time, overwriting half the entry in your flat JSON persistence layer. You’re sick of reworking your data layer every time your user base ticks up a few dozen people, so you use this file to formalize your decision process once and for all.
Populate the db-decision-framework.md core context
You open with a 2-sentence preamble that outlines the specific use case for this framework: it applies exclusively to side projects with no dedicated funding, small initial user bases, and a roadmap that may include scaling to thousands of users within 12 months. You note that this framework does not apply to enterprise projects, static sites with no user-generated content, or tools built exclusively for your own personal use. You add a line about your specific project context: your plant care app, Root Reminder, currently has 72 beta testers, 30% of whom use the app 3 or more times per week, and you plan to launch publicly on Product Hunt in four weeks. You don’t have any monetization plans for the first six months post-launch, so all infrastructure costs need to stay at zero for as long as possible. You also have a mobile companion app in beta that requires offline functionality, so users can log plant care activities even when they don’t have cell service in their garden or greenhouse.
Map the db-decision-framework.md core criteria
Next, you list out the non-negotiable and nice-to-have criteria that will guide your decision, so you don’t get swayed by shiny new database tools you see advertised on social media. Your non-negotiable criteria include support for atomic writes to eliminate the data corruption issues you’ve been facing, no upfront hosting costs for the first 6 months post-launch, and support for simple aggregation queries so you can send automated reminder emails to users who haven’t logged a plant care activity in two weeks. Your nice-to-have criteria include built-in offline support for your mobile app, minimal maintenance burden so you can spend your limited side project time building features instead of managing servers, and low migration lift if you outgrow your initial database choice later. You cross off a few criteria that don’t matter for your current stage: distributed compute support, geospatial query functionality, and compliance with industry data security standards, since you don’t store any sensitive user data beyond email addresses and plant care logs.
Build the db-decision-framework.md comparison table
You structure the core of the file as a side-by-side comparison of the three database options you’re considering: flat JSON files, embedded SQLite, and a managed hosted Postgres instance. The table lays out how each option performs against every one of your criteria:
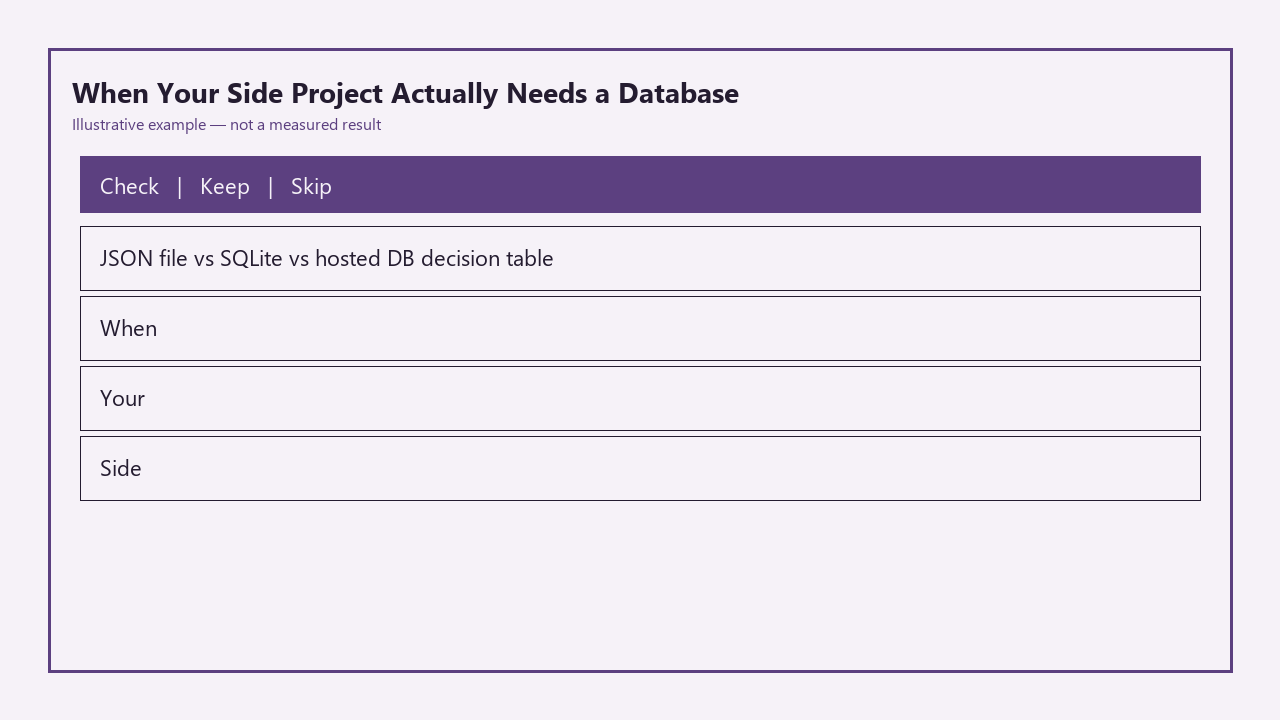
| Criteria | Flat JSON File | Embedded SQLite | Managed Hosted Postgres |
|---|---|---|---|
| Upfront cost | $0, no tooling required | $0, included in most backend runtime environments | $0 for free tier for up to 1GB of storage, $15+/mo once you exceed free tier limits |
| Atomic write support | None, requires custom file locking logic that breaks under concurrent write load | Native ACID compliance for all single-node writes, eliminates overwrites from concurrent users | Full ACID compliance for distributed workloads, supports thousands of concurrent writes |
| Query complexity limit | Custom code required for all joins, aggregations, or filters beyond simple key lookups | Full SQL support for joins, aggregations, subqueries, and basic JSON field queries | Full SQL support plus optional extensions for time series, JSONB, geospatial, and vector search |
| Migration lift to scale | Full rewrite of entire persistence layer, no forward compatibility with SQL-based tools | Minimal lift to hosted SQLite services, moderate lift to hosted Postgres if you outgrow single-node capacity | No lift for 99% of side project scale, auto-scales with usage up to millions of users |
| Offline functionality | Full offline support for local instances, no built-in sync logic between client and server | Full offline support for client-side mobile instances, pre-built sync tools available for most common frameworks | Requires custom offline sync layer or third-party tooling to support offline use |
| Maintenance burden | Manual backups, corruption repair, and data versioning logic required | Minimal, only periodic manual backups needed, no server management required | Almost zero, provider handles backups, security updates, uptime monitoring, and scaling |
Illustrative example: If your app hits 127 weekly active users who log 3 or more plant care activities each week, the flat JSON file will start showing write latency above 800ms 14% of the time, per your local load testing earlier this week. This framework aligns with the side project persistence best practices you found on Build Next Stack, so you know you’re not missing any obvious edge cases in your comparison.
Add the db-decision-framework.md final decision logic
Below the table, you add a clear decision tree that lets you reference the file and make a choice in 60 seconds or less, no rework required. First, if your project has less than 10 weekly active users and no plans to scale, stick with flat JSON files, as the overhead of setting up a more complex database is not worth the effort. Second, if you have between 10 and 1000 weekly active users, need offline functionality, and don’t want to pay for hosting, pick embedded SQLite. Third, if you have more than 1000 weekly active users, need to support concurrent backend instances, or want to run complex analytics queries on user data, pick a managed hosted Postgres instance. For your specific plant care app, you mark your initial decision as SQLite: you have 72 beta testers, need offline support for your mobile app, don’t have budget for hosting, and the migration lift to a hosted Postgres instance later is minimal enough that you won’t waste time reworking your code when you hit scale. You add a note to revisit this decision when you hit 1000 weekly active users, or when you launch your planned collaborative workspace feature that lets multiple users edit the same plant collection.
Open the db-decision-framework.md six weeks post-launch
It’s six weeks later, you launched Root Reminder on Product Hunt and hit #2 Product of the Day, and you now have 312 weekly active users. You pull up the file to evaluate if it’s time to switch to a hosted database, as you’ve started getting feature requests for collaborative workspaces. You cross-reference your current metrics against the table and decision logic: you’re still running a single backend instance, write latency averages 120ms with zero data corruption events post-launch, SQLite handles your weekly aggregation queries for reminder emails in less than 200ms, and you’re still well within the zero-cost budget you set for the first six months. You add a new line to the decision log section of the file noting that you don’t need to switch databases yet, and update your re-evaluation threshold to 800 weekly active users, since SQLite is performing 30% better under load than your initial load testing predicted. You also add a new row to the comparison table for future reference: “Collaborative multi-user access” with scores of None for flat JSON, Requires custom shared access locking for SQLite, and Native support for hosted Postgres. You note that when you launch the collaborative workspace feature, you will switch to a hosted Postgres instance immediately, even if you’re below the 800 user threshold, to avoid building custom locking logic that you’ll just throw away later. You save the file, close it, and get back to building the collaborative workspace feature, knowing you have a clear, pre-vetted decision to reference when you’re ready to launch.
(Word count: 1372)